Using AI for search to map B2B procurement questions starts with buyer evidence, not a list of AI-generated keywords. Collect what buying committees actually ask, organize those questions by role and decision stage, then test how generative engines answer them. The result should be a practical map connecting each question to an evidence gap, a responsible owner and a page that helps a buyer move forward.
This workflow is useful for MSPs, hotel groups, multi-location businesses, e-commerce suppliers and agencies selling services with several stakeholders involved.
Define the buying decision before researching questions
A procurement question map records the information buyers need to evaluate, approve and implement a purchase. Unlike a keyword list, it connects search behavior to a business decision.
Start with one buying situation. For example: an independent hotel group evaluating an MSP to support 12 properties. Its IT lead needs integration details, its finance team needs predictable costs and its operations director needs evidence that migration will not disrupt bookings.
Write a short research brief covering the buyer organization, purchase category, stakeholders, geography and operational constraints. Define the decision you want to support, such as reaching a qualified shortlist or approving a pilot.
Keep the scope narrow enough that the answers require specific evidence. “What is managed IT?” and “Can this provider support overnight incidents across our properties?” belong to different decision stages and need different pages.
AI for search becomes more useful when this buying context stays consistent across prompts. Otherwise, you may combine enterprise requirements, small-business questions and consumer searches into a map that serves none of them well.
Build a question map with AI for search
Collect questions from traceable sources
Begin with sales discovery notes, RFPs, support tickets, site-search logs and approved customer interviews. Search Console can reveal queries that already bring visitors to your pages, but it does not represent every question buyers ask an assistant.
Remove personal information, credentials, confidential pricing and customer-identifying details before sending material to an AI service. Use an approved environment for sensitive commercial information.
Give each question a source ID. Distinguish among a buyer’s exact words, an analyst’s paraphrase and an AI-generated hypothesis. Those labels prevent a plausible suggestion from becoming supposed customer evidence.
Use AI for search research to expand verified questions, not to invent demand. This prompt keeps the distinction explicit:
Context: A hotel group is evaluating an MSP for 12 properties.
Using the anonymized buyer questions below, group them by stakeholder and purchase stage.
Preserve the original wording and source ID.
Suggest missing follow-up questions in a separate section labeled Hypotheses.
For every question, identify the evidence needed to answer it.
Do not invent search volumes, customer statements, certifications or supplier capabilities.
Review the output with sales and delivery teams. They can identify questions that sound credible but rarely affect an actual purchase.
Map each question to a stakeholder and an answer asset
Separate questions by the decision they support, rather than by superficial wording. “What does onboarding cost?” is a commercial question. “Who migrates our monitoring agents?” concerns implementation ownership, even if both mention onboarding.
A useful first-pass map might look like this:
| Stakeholder | Procurement question | Decision supported | Evidence or page needed |
|---|---|---|---|
| IT lead | Does the service support our existing identity provider? | Technical fit | Integration documentation and limitations |
| Security reviewer | What access will technicians have to our systems? | Risk approval | Access-control overview and review process |
| Finance lead | Which charges sit outside the monthly fee? | Budget approval | Pricing assumptions and exclusions |
| Operations director | How will migration affect property operations? | Implementation approval | Phased rollout plan and responsibilities |
| Procurement manager | What are the termination and renewal terms? | Contract approval | Approved commercial terms or contract guidance |
| Executive sponsor | What evidence supports the business case? | Final authorization | Relevant case study with documented outcomes |
Using AI for search at this stage should expose missing evidence, not simply produce more topics. If the security question has no approved answer, the next task belongs to the security owner before it belongs to a writer.
Keep additional fields for source ID, confidence, target page, content owner and next action. Add a review date wherever facts can change, especially integrations, pricing and service coverage.
Reject clusters that match the topic but miss the buyer
AI-generated clusters can confuse a shared phrase with shared commercial intent. Review the underlying pages before accepting a proposed topic or competitor.
For an agency serving property-sector clients, “property solutions” could cover corporate property services or urgent consumer assistance. For example, Faster Property Solutions’ homeowner services address UK homeowners seeking repossession support and help selling a home. Those questions belong to a different audience from a corporate team procuring facilities management software.
The distinction matters because the expected answer, supporting evidence and conversion action are different. A consumer assistance query should not automatically become an enterprise supplier-evaluation topic.
When validating AI for search output, ask whether the question identifies the right buyer, decision and offer. Keep uncertain clusters in a review queue rather than publishing content against them immediately.
Test the questions across generative engines
A question map describes buyer needs. Testing reveals whether AI answers satisfy those needs and whether your brand appears accurately.
Choose engines your audience plausibly uses. ChatGPT, Gemini, Perplexity, Claude and Copilot support different research experiences depending on the product, account and search settings. Google AI Overviews appear within Google Search and do not trigger for every query.
For a manageable pilot, select 12 questions across the buying journey, test three engines and repeat each test twice. That produces 72 scheduled observations, an illustrative research design rather than a statistically representative market survey.
Run the baseline without naming your brand unless the question is explicitly about vendor validation. A prompt such as “Which MSPs support multi-property hotel groups in the UK?” measures discovery differently from “Does Supplier A support our identity provider?”
For a broader tool-selection framework, use this guide to choosing an AI search engine for brand research. Avoid assuming that one engine represents every buyer’s research experience.
Treat AI for search testing as a repeatable observation process. Save the prompt, date, product or model label when available, search mode, locale and response. Open cited pages to verify that they support the associated claims.
Record answer quality as well as brand presence
A mention alone can hide a serious gap. An assistant might name your company but describe the wrong service area, cite an outdated pricing page or attribute a competitor’s feature to you.
Record whether the answer mentions your brand, links to your domain, includes named competitors and answers the procurement question accurately. Capture the cited URL, not just its domain, so the content owner can investigate the actual source.
Use separate statuses for a completed answer, a technical failure and an unavailable search feature. For Google AI Overviews, record a non-trigger separately instead of calling it an incorrect answer.
Do not merge discovery prompts, branded validation prompts and troubleshooting questions into one performance score. They serve different commercial purposes.
The value of AI for search measurement is diagnostic: it should tell you whether a missing mention reflects absent evidence, weak retrieval, ambiguous positioning or an answer that favors another supplier’s documented capabilities.
Turn question gaps into pages AI and buyers can use
Publish the answer and its supporting evidence
Prioritize questions that block a shortlist, security review or buying approval. A high-stakes unanswered integration question can matter more than several broad educational topics.
Build a page around a clear answer, its scope, relevant limitations and the next action. For the hotel MSP example, explain supported identity systems, dependencies, the verification process and who handles exceptions. Do not claim compatibility before the delivery team confirms it.
Keep public summaries available where appropriate, while placing sensitive reports or detailed security documentation behind an approved access process. Making a claim retrievable does not require publishing confidential evidence.
Generative Engine Optimization, or GEO, focuses on making information usable in generated answers. Answer Engine Optimization, or AEO, emphasizes clear answers to explicit questions. Both depend on accurate content and sound technical SEO.
Applying AI for search insights means choosing the right answer asset. A finance question may need a pricing explanation, a technical question may need documentation and an implementation question may need a responsibility matrix. Not every gap needs another blog post.
Make the evidence accessible and unambiguous
Check crawlability before rewriting every page. Review robots rules, indexing directives, canonical URLs and whether essential content is available without authentication or a difficult interaction. Different crawlers have different purposes, so review access policies deliberately rather than allowing every bot by default.
Keep entity information consistent across the website: brand name, legal entity, service areas, locations and contact details. Inconsistency can make it harder for people and systems to distinguish your business from similarly named organizations.
Use structured data that accurately matches visible content. Organization, LocalBusiness and Product schema can clarify relevant facts, but markup does not guarantee inclusion or citation. Google’s guidance on AI features explains that established SEO practices remain relevant and that no special schema is required for those features.
Add descriptive internal links from service pages to supporting evidence. Improve page performance so buyers can reach and use that evidence without slow loading or unstable layouts. Neither action promises an AI citation, but both make the purchase journey more usable.
Technical work supports AI for search visibility by removing obstacles, not by guaranteeing recommendations. An llms.txt file is a proposed convention, not an access-control mechanism or proof that an assistant will ingest your pages. Use the AI search readiness checklist to organize these checks.
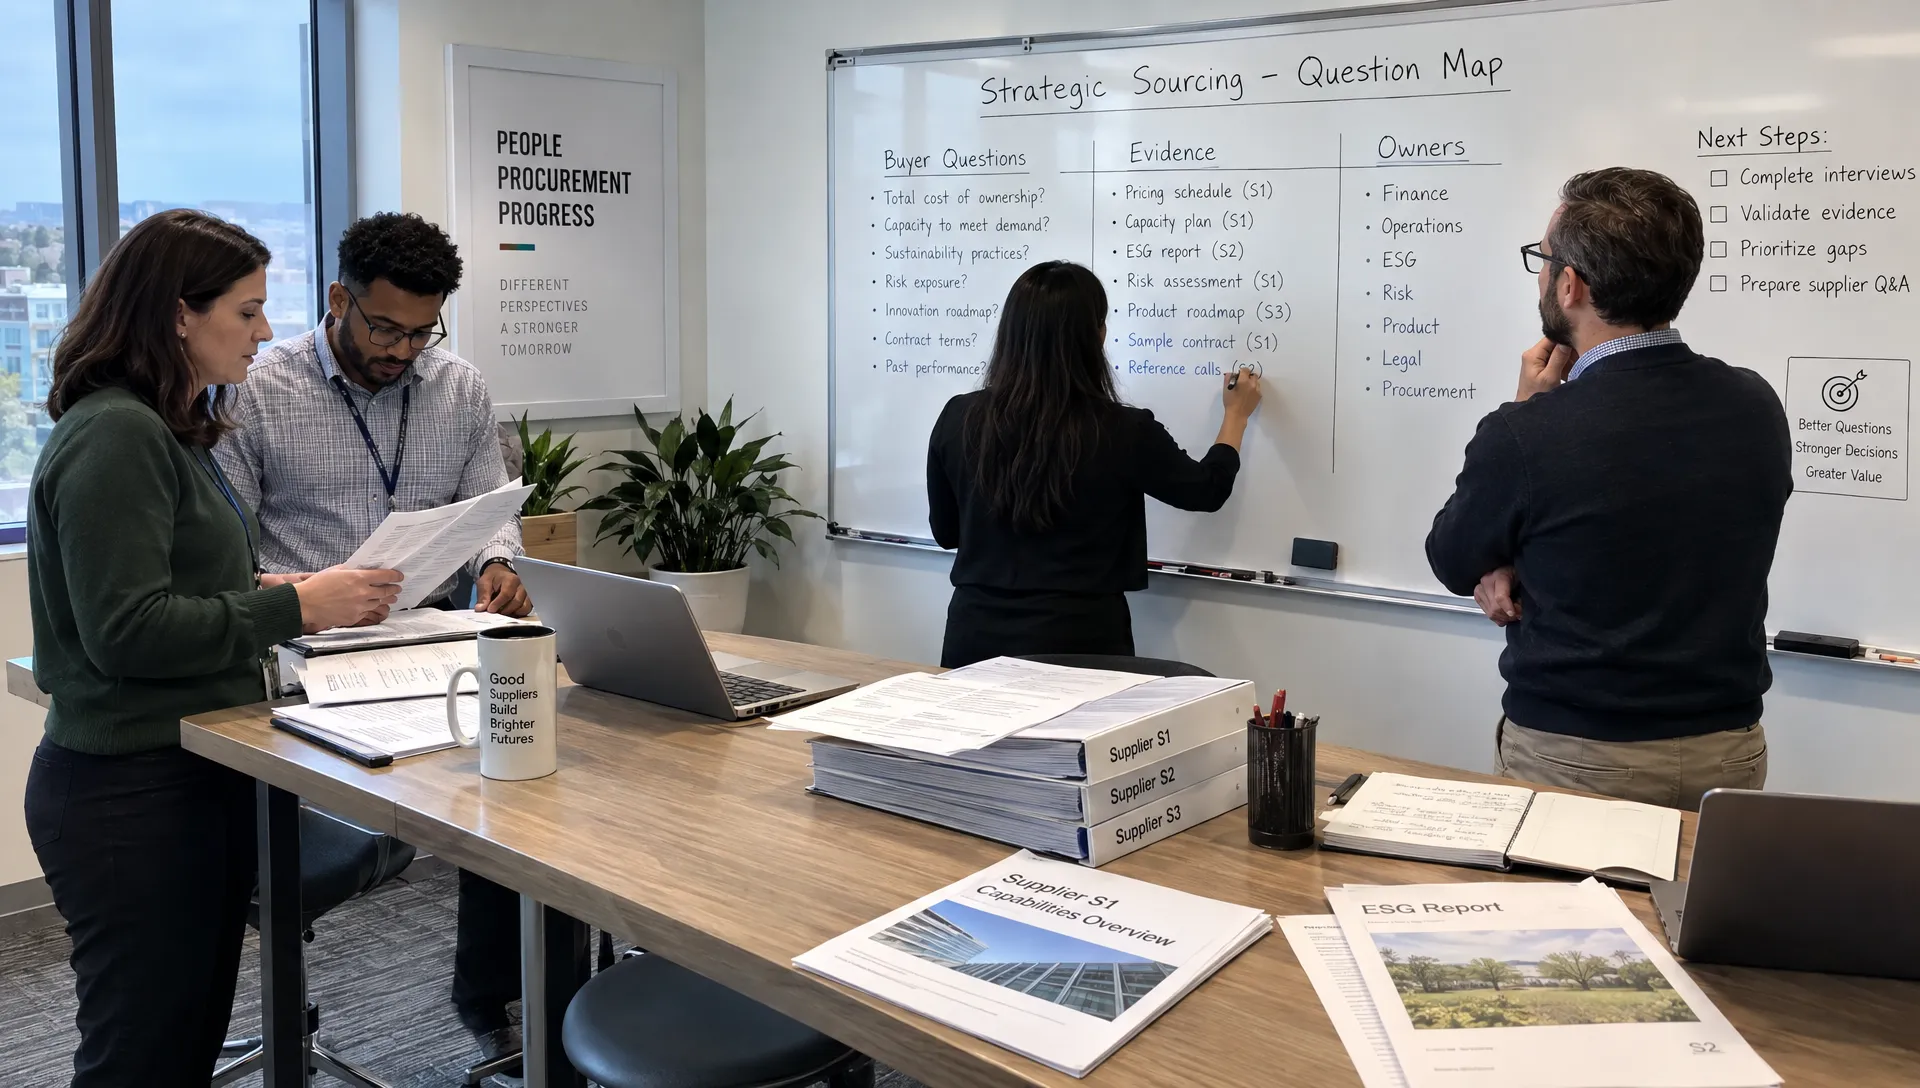
Measure coverage, visibility and commercial usefulness separately
Use a small scorecard with explicit denominators. This avoids treating every mention as success or presenting a test-panel result as market-wide demand.
| Metric | Calculation or assessment | What it tells you |
|---|---|---|
| Evidence coverage | Verified questions with an approved answer asset divided by verified questions | Whether buyers can find the information they need |
| Brand mention rate | Completed answers mentioning your brand divided by completed answers | How often the brand appears in the tested panel |
| Owned-domain citation rate | Completed answers citing your domain divided by completed answers | How often your pages become cited sources |
| Observed share of voice | Your brand-answer pairs divided by all tracked supplier-answer pairs | Your relative presence among tracked suppliers |
| Answer accuracy | Review of factual claims against approved evidence | Whether visibility is helping or misleading buyers |
Count each supplier once per answer when calculating share of voice. Keep the competitor set fixed and label the result as observed share of voice, not market share.
For illustration, if 72 completed answers contain 18 brand mentions and nine answers cite your domain, the rates are 25% and 12.5%. If tracked suppliers collectively appear in 90 supplier-answer pairs, your 18 pairs represent 20% observed share of voice.
Connect AI for search reporting to qualified inquiries, assisted conversions and sales feedback where evidence exists. Analytics alone will not capture every assistant-influenced purchase, so do not assign revenue to citations without a defensible attribution method.
Retest changes without overstating causality
Keep the original prompts as a fixed benchmark. Test new questions in a separate exploratory set so an expanding research scope does not distort the baseline.
After publishing changes, allow for discovery and indexing, then repeat the same conditions as closely as possible. Record which pages changed, which engines retrieved them and whether the answer became more accurate.
A before-and-after improvement is useful evidence, but it does not prove that one edit caused the change. Model updates, retrieval differences and competitor changes can also affect results.
Maintain an action log with an owner and status for each gap. This turns the map into a working queue for content, technical SEO, product specialists and sales enablement rather than a spreadsheet that stops at reporting.
Frequently asked questions
Can AI generate the entire procurement question map? It can draft and organize a map, but buyer records and subject-matter review should validate it. Label generated questions as hypotheses until evidence supports them.
How many procurement questions should we start with? Start with a small set that covers the important stakeholders and decisions. Twelve questions can support an initial test, but coverage matters more than reaching a particular number.
Is AI for search research a replacement for keyword research? No. Keyword research helps assess established search demand. Procurement question mapping adds stakeholder context, evidence requirements and visibility testing across generated answers.
Should every question become a separate page? No. Combine questions when they support the same decision and can be answered clearly together. Create separate pages when the audience, evidence or task differs materially.
Can schema or llms.txt guarantee a citation? No. Neither guarantees retrieval, inclusion or recommendation. Prioritize accessible, accurate evidence and measure what engines actually return.
Start with a free AI visibility audit
Start with a free AI visibility audit from CapstonAI to establish how your business currently appears across AI search experiences.
CapstonAI supports brand mention and citation tracking, competitor monitoring, prompt mapping and prioritized content recommendations. Use that baseline to choose one buying scenario, validate its questions and assign owners to the most consequential evidence gaps.
Your first deliverable should be specific: a question map that shows what buyers need to know, what AI currently answers and what your team will fix next.